Researchers have demonstrated that reinforcement learning can solve one of robotics' most persistent technical challenges: converting high-level movement commands into precise joint motions with millimeter accuracy.
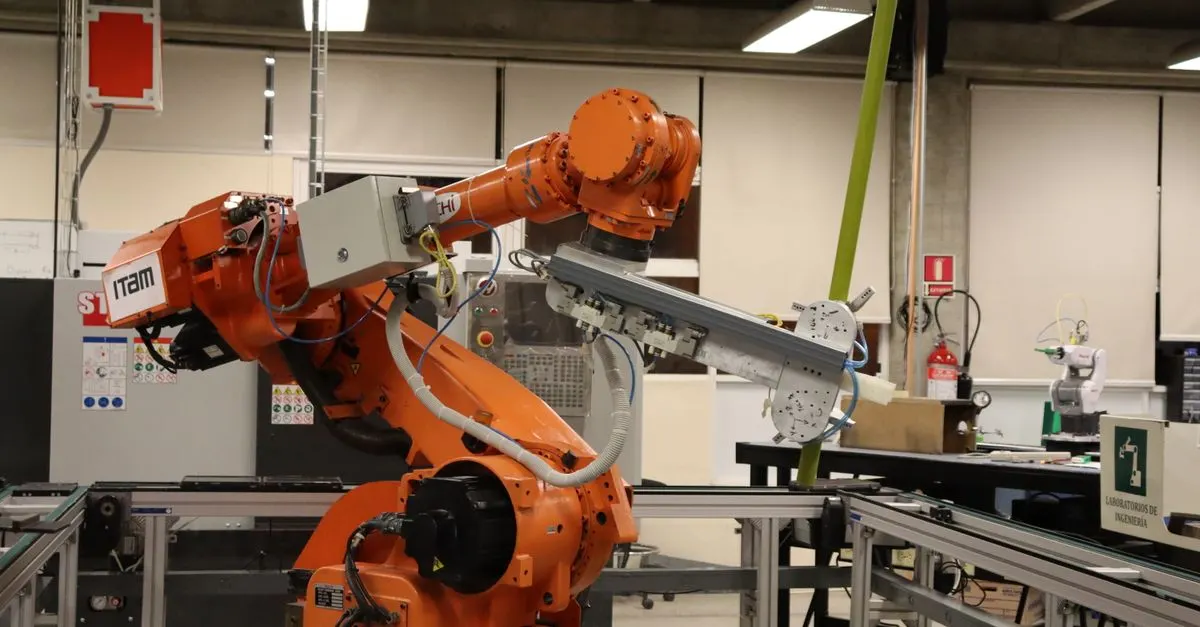
The breakthrough addresses a fundamental problem in robotic manipulation. When engineers program a robot arm to reach a specific location in space, the system must calculate which angles each joint needs to achieve. This inverse kinematics problem becomes exponentially harder when arms have redundant degrees of freedom or approach configurations where small changes in position produce large changes in joint angles, known as singularities. Current solutions require extensive hand-tuning and often fail to achieve sub-centimeter precision consistently.
According to arXiv, researchers from New York University and Shenji Wan's team have created PolicyIK, a reinforcement learning policy trained to handle inverse kinematics with remarkable precision. Rather than relying on analytical solutions or pre-programmed controllers, the system learns to iteratively adjust joint positions based on continuous feedback about where the end-effector actually reaches.
How PolicyIK Works
The system employs a clever two-part strategy. It tracks both the reference positions it sends to the robot's motors and the actual joint measurements, allowing it to maintain awareness of any persistent offset. The learning algorithm then uses dual-scale error correction: it detects large positional mistakes and corrects them aggressively while simultaneously managing smaller residual errors more delicately. This prevents overshooting while still converging toward the target.
The training process incorporates two reward signals. One encourages the robot to reach the desired tolerance threshold, while another rewards it for remaining within that threshold once achieved. This dual objective teaches the system both to move decisively toward targets and to hold position steadily.
Real-World Performance
In simulation tests, a single inference pass by the trained policy kept position errors below one millimeter and rotational errors under 0.2 degrees in over 93 percent of test cases. With an optimized deployment protocol, success rates rose to 98.9 percent. More significantly, when trained directly on physical hardware, PolicyIK outperformed four classical inverse kinematics controllers operating under identical time constraints.
The approach shows promise for vision-language-action systems, which increasingly power general-purpose robots. These foundation models can describe what actions to perform, but they rely on underlying inverse kinematics modules to translate those commands into actual robot motion. PolicyIK achieved 95.7 percent success executing end-effector commands from an existing VLA policy in simulated pick-and-place tasks.
Implications for Robot Learning
- Removes dependency on hand-tuned control parameters that vary between robot platforms
- Enables better transfer of robot policies across different arm morphologies
- Reduces data collection burden compared to traditional supervised learning approaches
- Demonstrates that learning-based approaches can achieve precision matching specialized algorithms
The researchers have released code publicly, allowing other teams to build on the approach. This opens new possibilities for deploying robot arms with minimal platform-specific engineering, potentially accelerating the development of more capable manipulation systems across industry and research settings.